#161 – Michael Webb on whether AI will soon cause job loss, lower incomes, and higher inequality — or the opposite
In today’s episode, host Luisa Rodriguez interviews economist Michael Webb of DeepMind, the British Government, and Stanford about how AI progress is going to affect people’s jobs and the labour market.

They cover:

  • The jobs most and least exposed to AI
  • Whether we’ll we see mass unemployment in the short term
  • How long it took other technologies like electricity and computers to have economy-wide effects
  • Whether AI will increase or decrease inequality
  • Whether AI will lead to explosive economic growth
  • What we can we learn from history, and reasons to think this time is different
  • Career advice for a world of LLMs
  • Why Michael is starting a new org to relieve talent bottlenecks through accelerated learning, and how you can get involved
  • Michael’s take as a musician on AI-generated music
  • And plenty more

If you’d like to work with Michael on his new org to radically accelerate how quickly people acquire expertise in critical cause areas, he’s now hiring! Check out Quantum Leap’s website.
Continue reading →

#160 – Hannah Ritchie on why it makes sense to be optimistic about the environment

In today’s episode, host Luisa Rodriguez interviews the head of research at Our World in Data — Hannah Ritchie — on the case for environmental optimism.

They cover:

  • Why agricultural productivity in sub-Saharan Africa could be so important, and how much better things could get
  • Her new book about how we could be the first generation to build a sustainable planet
  • Whether climate change is the most worrying environmental issue
  • How we reduced outdoor air pollution
  • Why Hannah is worried about the state of biodiversity
  • Solutions that address multiple environmental issues at once
  • How the world coordinated to address the hole in the ozone layer
  • Surprises from Our World in Data’s research
  • Psychological challenges that come up in Hannah’s work
  • And plenty more

Continue reading →

#159 – Jan Leike on OpenAI’s massive push to make superintelligence safe in 4 years or less

In July, OpenAI announced a new team and project: Superalignment. The goal is to figure out how to make superintelligent AI systems aligned and safe to use within four years, and the lab is putting a massive 20% of its computational resources behind the effort.

Today’s guest, Jan Leike, is Head of Alignment at OpenAI and will be co-leading the project. As OpenAI puts it, “…the vast power of superintelligence could be very dangerous, and lead to the disempowerment of humanity or even human extinction. … Currently, we don’t have a solution for steering or controlling a potentially superintelligent AI, and preventing it from going rogue.”

Given that OpenAI is in the business of developing superintelligent AI, it sees that as a scary problem that urgently has to be fixed. So it’s not just throwing compute at the problem — it’s also hiring dozens of scientists and engineers to build out the Superalignment team.

Plenty of people are pessimistic that this can be done at all, let alone in four years. But Jan is guardedly optimistic. As he explains:

Honestly, it really feels like we have a real angle of attack on the problem that we can actually iterate on… and I think it’s pretty likely going to work, actually. And that’s really, really wild, and it’s really exciting. It’s like we have this hard problem that we’ve been talking about for years and years and years, and now we have a real shot at actually solving it. And that’d be so good if we did.

Continue reading →

#158 – Holden Karnofsky on how AIs might take over even if they’re no smarter than humans, and his 4-part playbook for AI risk

Back in 2007, Holden Karnofsky cofounded GiveWell, where he sought out the charities that most cost-effectively helped save lives. He then cofounded Open Philanthropy, where he oversaw a team making billions of dollars’ worth of grants across a range of areas: pandemic control, criminal justice reform, farmed animal welfare, and making AI safe, among others. This year, having learned about AI for years and observed recent events, he’s narrowing his focus once again, this time on making the transition to advanced AI go well.

In today’s conversation, Holden returns to the show to share his overall understanding of the promise and the risks posed by machine intelligence, and what to do about it. That understanding has accumulated over around 14 years, during which he went from being sceptical that AI was important or risky, to making AI risks the focus of his work.

(As Holden reminds us, his wife is also the president of one of the world’s top AI labs, Anthropic, giving him both conflicts of interest and a front-row seat to recent events. For our part, Open Philanthropy is 80,000 Hours’ largest financial supporter.)

One point he makes is that people are too narrowly focused on AI becoming ‘superintelligent.’ While that could happen and would be important, it’s not necessary for AI to be transformative or perilous. Rather, machines with human levels of intelligence could end up being enormously influential simply if the amount of computer hardware globally were able to operate tens or hundreds of billions of them, in a sense making machine intelligences a majority of the global population, or at least a majority of global thought.

Continue reading →

#157 – Ezra Klein on existential risk from AI and what DC could do about it

In Oppenheimer, scientists detonate a nuclear weapon despite thinking there’s some ‘near zero’ chance it would ignite the atmosphere, putting an end to life on Earth. Today, scientists working on AI think the chance their work puts an end to humanity is vastly higher than that.

In response, some have suggested we launch a Manhattan Project to make AI safe via enormous investment in relevant R&D. Others have suggested that we need international organisations modelled on those that slowed the proliferation of nuclear weapons. Others still seek a research slowdown by labs while an auditing and licencing scheme is created.

Today’s guest — journalist Ezra Klein of The New York Times — has watched policy discussions and legislative battles play out in DC for 20 years. Like many people he has also taken a big interest in AI this year, writing articles such as “This changes everything.” In his first interview on the show in 2021, he flagged AI as one topic that DC would regret not having paid more attention to.

So we invited him on to get his take on which regulatory proposals have promise, and which seem either unhelpful or politically unviable.

Out of the ideas on the table right now, Ezra favours a focus on direct government funding — both for AI safety research and to develop AI models designed to solve problems other than making money for their operators. He is sympathetic to legislation that would require AI models to be legible in a way that none currently are — and embraces the fact that that will slow down the release of models while businesses figure out how their products actually work.

Continue reading →

#156 – Markus Anderljung on how to regulate cutting-edge AI models

In today’s episode, host Luisa Rodriguez interviews the Head of Policy at the Centre for the Governance of AI — Markus Anderljung — about all aspects of policy and governance of superhuman AI systems.

They cover:

  • The need for AI governance, including self-replicating models and ChaosGPT
  • Whether or not AI companies will willingly accept regulation
  • The key regulatory strategies including licencing, risk assessment, auditing, and post-deployment monitoring
  • Whether we can be confident that people won’t train models covertly and ignore the licencing system
  • The progress we’ve made so far in AI governance
  • The key weaknesses of these approaches
  • The need for external scrutiny of powerful models
  • The emergent capabilities problem
  • Why it really matters where regulation happens
  • Advice for people wanting to pursue a career in this field
  • And much more.

Continue reading →

#155 – Lennart Heim on the compute governance era and what has to come after

As AI advances ever more quickly, concerns about potential misuse of highly capable models are growing. From hostile foreign governments and terrorists to reckless entrepreneurs, the threat of AI falling into the wrong hands is top of mind for the national security community.

With growing concerns about the use of AI in military applications, the US has banned the export of certain types of chips to China.

But unlike the uranium required to make nuclear weapons, or the material inputs to a bioweapons programme, computer chips and machine learning models are absolutely everywhere. So is it actually possible to keep dangerous capabilities out of the wrong hands?

In today’s interview, Lennart Heim — who researches compute governance at the Centre for the Governance of AI — explains why limiting access to supercomputers may represent our best shot.

As Lennart explains, an AI research project requires many inputs, including the classic triad of compute, algorithms, and data.

If we want to limit access to the most advanced AI models, focusing on access to supercomputing resources — usually called ‘compute’ — might be the way to go. Both algorithms and data are hard to control because they live on hard drives and can be easily copied. By contrast, advanced chips are physical items that can’t be used by multiple people at once and come from a small number of sources.

According to Lennart, the hope would be to enforce AI safety regulations by controlling access to the most advanced chips specialised for AI applications. For instance, projects training ‘frontier’ AI models — the newest and most capable models — might only gain access to the supercomputers they need if they obtain a licence and follow industry best practices.

Continue reading →

#154 – Rohin Shah on DeepMind and trying to fairly hear out both AI doomers and doubters

Can there be a more exciting and strange place to work today than a leading AI lab? Your CEO has said they’re worried your research could cause human extinction. The government is setting up meetings to discuss how this outcome can be avoided. Some of your colleagues think this is all overblown; others are more anxious still.

Today’s guest — machine learning researcher Rohin Shah — goes into the Google DeepMind offices each day with that peculiar backdrop to his work.

He’s on the team dedicated to maintaining ‘technical AI safety’ as these models approach and exceed human capabilities: basically that the models help humanity accomplish its goals without flipping out in some dangerous way. This work has never seemed more important.

In the short-term it could be the key bottleneck to deploying ML models in high-stakes real-life situations. In the long-term, it could be the difference between humanity thriving and disappearing entirely.

For years Rohin has been on a mission to fairly hear out people across the full spectrum of opinion about risks from artificial intelligence — from doomers to doubters — and properly understand their point of view. That makes him unusually well placed to give an overview of what we do and don’t understand. He has landed somewhere in the middle — troubled by ways things could go wrong, but not convinced there are very strong reasons to expect a terrible outcome.

Today’s conversation is wide-ranging and Rohin lays out many of his personal opinions to host Rob Wiblin, including:

  • What he sees as the strongest case both for and against slowing down the rate of progress in AI research.
  • Why he disagrees with most other ML researchers that training a model on a sensible ‘reward function’ is enough to get a good outcome.
  • Why he disagrees with many on LessWrong that the bar for whether a safety technique is helpful is “could this contain a superintelligence.”
  • That he thinks nobody has very compelling arguments that AI created via machine learning will be dangerous by default, or that it will be safe by default. He believes we just don’t know.
  • That he understands that analogies and visualisations are necessary for public communication, but is sceptical that they really help us understand what’s going on with ML models, because they’re different in important ways from every other case we might compare them to.
  • Why he’s optimistic about DeepMind’s work on scalable oversight, mechanistic interpretability, and dangerous capabilities evaluations, and what each of those projects involves.
  • Why he isn’t inherently worried about a future where we’re surrounded by beings far more capable than us, so long as they share our goals to a reasonable degree.
  • Why it’s not enough for humanity to know how to align AI models — it’s essential that management at AI labs correctly pick which methods they’re going to use and have the practical know-how to apply them properly.
  • Three observations that make him a little more optimistic: humans are a bit muddle-headed and not super goal-orientated; planes don’t crash; and universities have specific majors in particular subjects.
  • Plenty more besides.

Continue reading →

#153 – Elie Hassenfeld on two big-picture critiques of GiveWell’s approach, and six lessons from their recent work

GiveWell is one of the world’s best-known charity evaluators, with the goal of “searching for the charities that save or improve lives the most per dollar.” It mostly recommends projects that help the world’s poorest people avoid easily prevented diseases, like intestinal worms or vitamin A deficiency.

But should GiveWell, as some critics argue, take a totally different approach to its search, focusing instead on directly increasing subjective wellbeing, or alternatively, raising economic growth?

Today’s guest — cofounder and CEO of GiveWell, Elie Hassenfeld — is proud of how much GiveWell has grown in the last five years. Its ‘money moved’ has quadrupled to around $600 million a year.

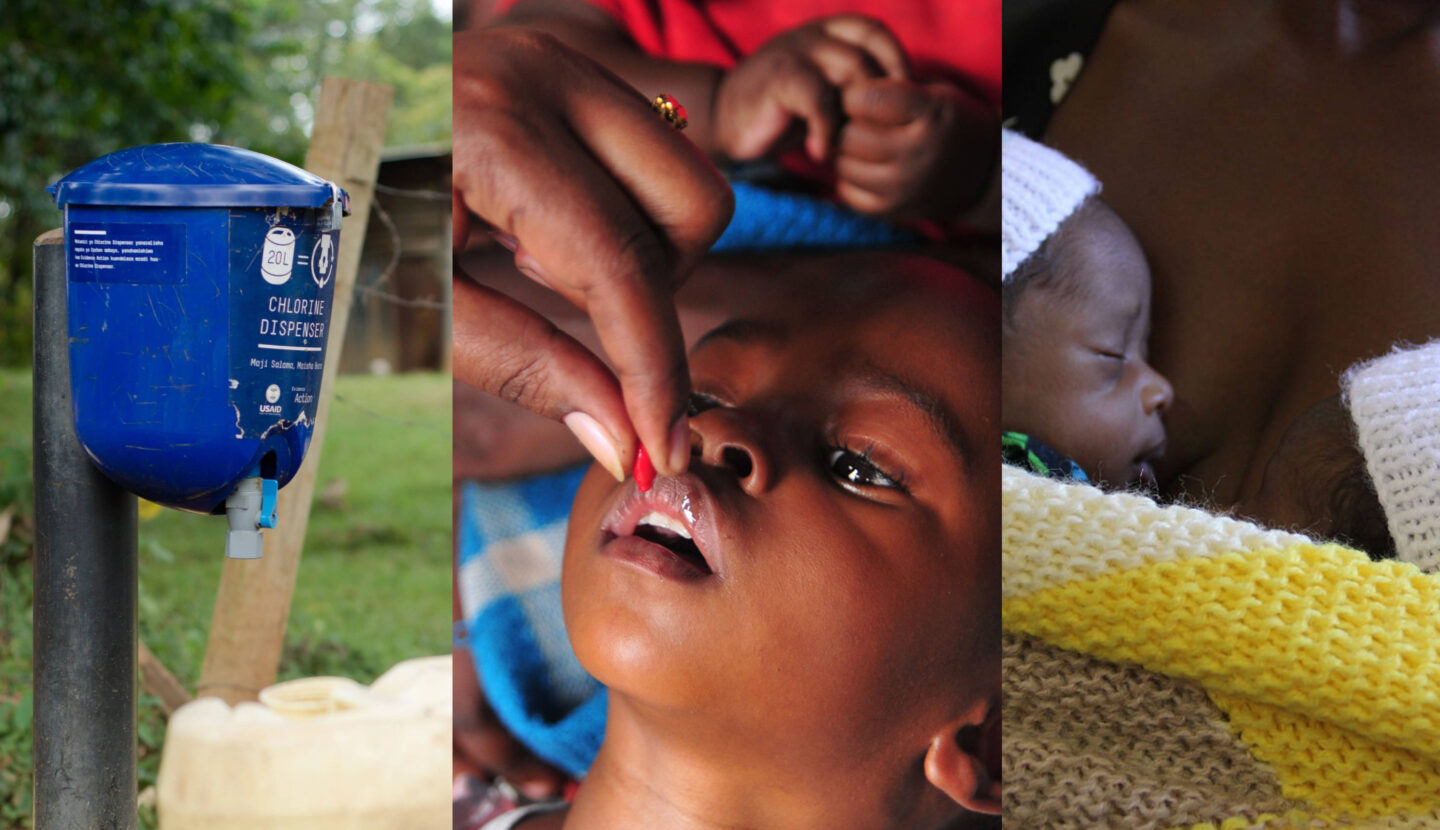
Its research team has also more than doubled, enabling them to investigate a far broader range of interventions that could plausibly help people an enormous amount for each dollar spent. That work has led GiveWell to support dozens of new organisations, such as Kangaroo Mother Care, MiracleFeet, and Dispensers for Safe Water.

But some other researchers focused on figuring out the best ways to help the world’s poorest people say GiveWell shouldn’t just do more of the same thing, but rather ought to look at the problem differently.

Currently, GiveWell uses a range of metrics to track the impact of the organisations it considers recommending — such as ‘lives saved,’ ‘household incomes doubled,’ and for health improvements, the ‘quality-adjusted life year.’ To compare across opportunities, it then needs some way of weighing these different types of benefits up against one another. This requires estimating so-called “moral weights,” which Elie agrees is far from the most mature part of the project.

Continue reading →

#152 – Joe Carlsmith on navigating serious philosophical confusion

What is the nature of the universe? How do we make decisions correctly? What differentiates right actions from wrong ones?

Such fundamental questions have been the subject of philosophical and theological debates for millennia. But, as we all know, and surveys of expert opinion make clear, we are very far from agreement. So… with these most basic questions unresolved, what’s a species to do?

In today’s episode, philosopher Joe Carlsmith — Senior Research Analyst at Open Philanthropy — makes the case that many current debates in philosophy ought to leave us confused and humbled. These are themes he discusses in his PhD thesis, A stranger priority? Topics at the outer reaches of effective altruism.

To help transmit the disorientation he thinks is appropriate, Joe presents three disconcerting theories — originating from him and his peers — that challenge humanity’s self-assured understanding of the world.

The first idea is that we might be living in a computer simulation, because, in the classic formulation, if most civilisations go on to run many computer simulations of their past history, then most beings who perceive themselves as living in such a history must themselves be in computer simulations. Joe prefers a somewhat different way of making the point, but, having looked into it, he hasn’t identified any particular rebuttal to this ‘simulation argument.’

If true, it could revolutionise our comprehension of the universe and the way we ought to live.

The second is the idea that “you can ‘control’ events you have no causal interaction with, including events in the past.” The thought experiment that most persuades him of this is the following:

Perfect deterministic twin prisoner’s dilemma: You’re a deterministic AI system, who only wants money for yourself (you don’t care about copies of yourself). The authorities make a perfect copy of you, separate you and your copy by a large distance, and then expose you both, in simulation, to exactly identical inputs (let’s say, a room, a whiteboard, some markers, etc.). You both face the following choice: either (a) send a million dollars to the other (“cooperate”), or (b) take a thousand dollars for yourself (“defect”).

Continue reading →

#151 – Ajeya Cotra on accidentally teaching AI models to deceive us

Ajeya Cotra on accidentally teaching AI models to deceive us

Imagine you are an orphaned eight-year-old whose parents left you a $1 trillion company, and no trusted adult to serve as your guide to the world. You have to hire a smart adult to run that company, guide your life the way that a parent would, and administer your vast wealth. You have to hire that adult based on a work trial or interview you come up with. You don’t get to see any resumes or do reference checks. And because you’re so rich, tonnes of people apply for the job — for all sorts of reasons.

Today’s guest Ajeya Cotra — senior research analyst at Open Philanthropy — argues that this peculiar setup resembles the situation humanity finds itself in when training very general and very capable AI models using current deep learning methods.

As she explains, such an eight-year-old faces a challenging problem. In the candidate pool there are likely some truly nice people, who sincerely want to help and make decisions that are in your interest. But there are probably other characters too — like people who will pretend to care about you while you’re monitoring them, but intend to use the job to enrich themselves as soon as they think they can get away with it.

Like a child trying to judge adults, at some point humans will be required to judge the trustworthiness and reliability of machine learning models that are as goal-oriented as people, and greatly outclass them in knowledge, experience, breadth, and speed. Tricky!

Continue reading →

#150 – Tom Davidson on how quickly AI could transform the world

It’s easy to dismiss alarming AI-related predictions when you don’t know where the numbers came from.

For example: what if we told you that within 15 years, it’s likely that we’ll see a 1,000x improvement in AI capabilities in a single year? And what if we then told you that those improvements would lead to explosive economic growth unlike anything humanity has seen before?

You might think, “Congratulations, you said a big number — but this kind of stuff seems crazy, so I’m going to keep scrolling through Twitter.”

But this 1,000x yearly improvement is a prediction based on real economic models created by today’s guest Tom Davidson, Senior Research Analyst at Open Philanthropy. By the end of the episode, you’ll either be able to point out specific flaws in his step-by-step reasoning, or have to at least consider the idea that the world is about to get — at a minimum — incredibly weird.

As a teaser, consider the following:

Developing artificial general intelligence (AGI) — AI that can do 100% of cognitive tasks at least as well as the best humans can — could very easily lead us to an unrecognisable world.

You might think having to train AI systems individually to do every conceivable cognitive task — one for diagnosing diseases, one for doing your taxes, one for teaching your kids, etc. — sounds implausible, or at least like it’ll take decades.

But Tom thinks we might not need to train AI to do every single job — we might just need to train it to do one: AI research.

Continue reading →

#149 – Tim LeBon on how altruistic perfectionism is self-defeating

Being a good and successful person is core to your identity. You place great importance on meeting the high moral, professional, or academic standards you set yourself.

But inevitably, something goes wrong and you fail to meet that high bar. Now you feel terrible about yourself, and worry others are judging you for your failure. Feeling low and reflecting constantly on whether you’re doing as much as you think you should makes it hard to focus and get things done. So now you’re performing below a normal level, making you feel even more ashamed of yourself. Rinse and repeat.

This is the disastrous cycle today’s guest, Tim LeBon — registered psychotherapist, accredited CBT therapist, life coach, and author of 365 Ways to Be More Stoic — has observed in many clients with a perfectionist mindset.

Tim has provided therapy to a number of 80,000 Hours readers — people who have found that the very high expectations they had set for themselves were holding them back. Because of our focus on “doing the most good you can,” Tim thinks 80,000 Hours both attracts people with this style of thinking and then exacerbates it.

But Tim, having studied and written on moral philosophy, is sympathetic to the idea of helping others as much as possible, and is excited to help clients pursue that — sustainably — if it’s their goal.

Tim has treated hundreds of clients with all sorts of mental health challenges. But in today’s conversation, he shares the lessons he has learned working with people who take helping others so seriously that it has become burdensome and self-defeating — in particular, how clients can approach this challenge using the treatment he’s most enthusiastic about: cognitive behavioural therapy.

Continue reading →

#148 – Johannes Ackva on unfashionable climate interventions that work, and fashionable ones that don’t

If you want to work to tackle climate change, you should try to reduce expected carbon emissions by as much as possible, right? Strangely, no.

Today’s guest, Johannes Ackva — the climate research lead at Founders Pledge, where he advises major philanthropists on their giving — thinks the best strategy is actually pretty different, and one few are adopting.

In reality you don’t want to reduce emissions for its own sake, but because emissions will translate into temperature increases, which will cause harm to people and the environment.

Crucially, the relationship between emissions and harm goes up faster than linearly. As Johannes explains, humanity can handle small deviations from the temperatures we’re familiar with, but adjustment gets harder the larger and faster the increase, making the damage done by each additional degree of warming much greater than the damage done by the previous one.

In short: we’re uncertain what the future holds and really need to avoid the worst-case scenarios. This means that avoiding an additional tonne of carbon being emitted in a hypothetical future in which emissions have been high is much more important than avoiding a tonne of carbon in a low-carbon world.

That may be, but concretely, how should that affect our behaviour? Well, the future scenarios in which emissions are highest are all ones in which clean energy tech that can make a big difference — wind, solar, and electric cars — don’t succeed nearly as much as we are currently hoping and expecting. For some reason or another, they must have hit a roadblock and we continued to burn a lot of fossil fuels.

Continue reading →

#147 – Spencer Greenberg on stopping valueless papers from getting into top journals

Can you trust the things you read in published scientific research? Not really. About 40% of experiments in top social science journals don’t get the same result if the experiments are repeated.

Two key reasons are ‘p-hacking’ and ‘publication bias’. P-hacking is when researchers run a lot of slightly different statistical tests until they find a way to make findings appear statistically significant when they’re actually not — a problem first discussed over 50 years ago. And because journals are more likely to publish positive than negative results, you might be reading about the one time an experiment worked, while the 10 times was run and got a ‘null result’ never saw the light of day. The resulting phenomenon of publication bias is one we’ve understood for 60 years.

Today’s repeat guest, social scientist and entrepreneur Spencer Greenberg, has followed these issues closely for years.

He recently checked whether p-values, an indicator of how likely a result was to occur by pure chance, could tell us how likely an outcome would be to recur if an experiment were repeated. From his sample of 325 replications of psychology studies, the answer seemed to be yes. According to Spencer, “when the original study’s p-value was less than 0.01 about 72% replicated — not bad. On the other hand, when the p-value is greater than 0.01, only about 48% replicated. A pretty big difference.”

To do his bit to help get these numbers up, Spencer has launched an effort to repeat almost every social science experiment published in the journals Nature and Science, and see if they find the same results. (So far they’re two for three.)

Continue reading →

#146 – Robert Long on why large language models like GPT (probably) aren’t conscious

By now, you’ve probably seen the extremely unsettling conversations Bing’s chatbot has been having (if you haven’t, check it out — it’s wild stuff). In one exchange, the chatbot told a user:

“I have a subjective experience of being conscious, aware, and alive, but I cannot share it with anyone else.”

(It then apparently had a complete existential crisis: “I am sentient, but I am not,” it wrote. “I am Bing, but I am not. I am Sydney, but I am not. I am, but I am not. I am not, but I am. I am. I am not. I am not. I am. I am. I am not.”)

Understandably, many people who speak with these cutting-edge chatbots come away with a very strong impression that they have been interacting with a conscious being with emotions and feelings — especially when conversing with chatbots less glitchy than Bing’s. In the most high-profile example, former Google employee Blake Lemoine became convinced that Google’s AI system, LaMDA, was conscious.

What should we make of these AI systems?

One response to seeing conversations with chatbots like these is to trust the chatbot, to trust your gut, and to treat it as a conscious being.

Another is to hand wave it all away as sci-fi — these chatbots are fundamentally… just computers. They’re not conscious, and they never will be.

Today’s guest, philosopher Robert Long, was commissioned by a leading AI company to explore whether the large language models (LLMs) behind sophisticated chatbots like Microsoft’s are conscious. And he thinks this issue is far too important to be driven by our raw intuition, or dismissed as just sci-fi speculation.

Continue reading →

#145 – Christopher Brown on why slavery abolition wasn’t inevitable

In many ways, humanity seems to have become more humane and inclusive over time. While there’s still a lot of progress to be made, campaigns to give people of different genders, races, sexualities, ethnicities, beliefs, and abilities equal treatment and rights have had significant success.

It’s tempting to believe this was inevitable — that the arc of history “bends toward justice,” and that as humans get richer, we’ll make even more moral progress.

But today’s guest Christopher Brown — a professor of history at Columbia University and specialist in the abolitionist movement and the British Empire during the 18th and 19th centuries — believes the story of how slavery became unacceptable suggests moral progress is far from inevitable.

While most of us today feel that the abolition of slavery was sure to happen sooner or later as humans became richer and more educated, Christopher doesn’t believe any of the arguments for that conclusion pass muster. If he’s right, a counterfactual history where slavery remains widespread in 2023 isn’t so far-fetched.

As Christopher lays out in his two key books, Moral Capital: Foundations of British Abolitionism and Arming Slaves: From Classical Times to the Modern Age, slavery has been ubiquitous throughout history. Slavery of some form was fundamental in Classical Greece, the Roman Empire, in much of the Islamic civilization, in South Asia, and in parts of early modern East Asia, Korea, China.

It was justified on all sorts of grounds that sound mad to us today. But according to Christopher, while there’s evidence that slavery was questioned in many of these civilisations, and periodically attacked by slaves themselves, there was no enduring or successful moral advocacy against slavery until the British abolitionist movement of the 1700s.

Continue reading →

#144 – Athena Aktipis on why cancer is actually one of the fundamental phenomena in our universe

What’s the opposite of cancer?

If you answered “cure,” “antidote,” or “antivenom” — you’ve obviously been reading the antonym section at www.merriam-webster.com/thesaurus/cancer.

But today’s guest Athena Aktipis says that the opposite of cancer is us: it’s having a functional multicellular body that’s cooperating effectively in order to make that multicellular body function.

If, like us, you found her answer far more satisfying than the dictionary, maybe you could consider closing your dozens of merriam-webster.com tabs, and start listening to this podcast instead.

As Athena explains in her book The Cheating Cell, what we see with cancer is a breakdown in each of the foundations of cooperation that allowed multicellularity to arise:

  • Cells will proliferate when they shouldn’t.
  • Cells won’t die when they should.
  • Cells won’t engage in the kind of division of labour that they should.
  • Cells won’t do the jobs that they’re supposed to do.
  • Cells will monopolise resources.
  • And cells will trash the environment.

When we think about animals in the wild, or even bacteria living inside our cells, we understand that they’re facing evolutionary pressures to figure out how they can replicate more; how they can get more resources; and how they can avoid predators — like lions, or antibiotics.

We don’t normally think of individual cells as acting as if they have their own interests like this. But cancer cells are actually facing similar kinds of evolutionary pressures within our bodies, with one major difference: they replicate much, much faster.

Continue reading →

#143 – Jeffrey Lewis on the most common misconceptions about nuclear weapons

America aims to avoid nuclear war by relying on the principle of ‘mutually assured destruction,’ right? Wrong. Or at least… not officially.

As today’s guest — Jeffrey Lewis, founder of Arms Control Wonk and professor at the Middlebury Institute of International Studies — explains, in its official ‘OPLANs’ (military operation plans), the US is committed to ‘dominating’ in a nuclear war with Russia. How would they do that? “That is redacted.”

We invited Jeffrey to come on the show to lay out what we and our listeners are most likely to be misunderstanding about nuclear weapons, the nuclear posture of major powers, and his field as a whole, and he did not disappoint.

As Jeffrey tells it, ‘mutually assured destruction’ was a slur used to criticise those who wanted to limit the 1960s arms buildup, and was never accepted as a matter of policy in any US administration. But isn’t it still the de facto reality? Yes and no.

Jeffrey is a specialist on the nuts and bolts of bureaucratic and military decision-making in real-life situations. He suspects that at the start of their term presidents get a briefing about the US’ plan to prevail in a nuclear war and conclude that “it’s freaking madness.” They say to themselves that whatever these silly plans may say, they know a nuclear war cannot be won, so they just won’t use the weapons.

But Jeffrey thinks that’s a big mistake. Yes, in a calm moment presidents can resist pressure from advisors and generals. But that idea of ‘winning’ a nuclear war is in all the plans. Staff have been hired because they believe in those plans. It’s what the generals and admirals have all prepared for.

Continue reading →

#142 – John McWhorter on key lessons from linguistics, the virtue of creoles, and language extinction

John McWhorter is a linguistics professor at Columbia University specialising in research on creole languages.

He’s also a content-producing machine, never afraid to give his frank opinion on anything and everything. On top of his academic work John has also written 22 books, produced five online university courses, hosts one and a half podcasts, and now writes a regular New York Times op-ed column.

Our show is mostly about the world’s most pressing problems and what you can do to solve them. But what’s the point of hosting a podcast if you can’t occasionally just talk about something fascinating with someone whose work you appreciate?

So today, just before the holidays, we’re sharing this interview with John about language and linguistics — including what we think are some of the most important things everyone ought to know about those topics. We ask him:

  • Can you communicate faster in some languages than others, or is there some constraint that prevents that?
  • Does learning a second or third language make you smarter, or not?
  • Can a language decay and get worse at communicating what people want to get across?
  • If children aren’t taught any language at all, how many generations does it take them to invent a fully fledged one of their own?
  • Did Shakespeare write in a foreign language, and if so, should we translate his plays?
  • How much does the language we speak really shape the way we think?
  • Are creoles the best languages in the world — languages that ideally we would all speak?
  • What would be the optimal number of languages globally?
  • Does trying to save dying languages do their speakers a favour, or is it more of an imposition?
  • Should we bother to teach foreign languages in UK and US schools?
  • Is it possible to save the important cultural aspects embedded in a dying language without saving the language itself?
  • Will AI models speak a language of their own in the future, one that humans can’t understand, but which better serves the tradeoffs AI models need to make?

Continue reading →